Showing posts with label High Availability. Show all posts

Intel NUCs - Another Take on EXPTA Home Lab Servers. Builds and Parts Lists.

Friday, June 3, 2016

Own a blistering fast two-node Hyper-V lab cluster for under $1,680!

Today, I'm doing another take on my well-know home Hyper-V lab server series. My latest Gen7 builds are single-server builds with 64GB-128GB ranging from $920-$1,915 per server. That gives you super-high density in a single small, but powerful, server. In this article I'll show you how to create a two-node Hyper-V cluster using Intel NUC servers so you can learn how to use Hyper-V replication and provide true high availability and fail-over.

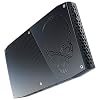
The Intel NUC (Next Unit of Computing) is a Mini PC with the power of a desktop, packing powerful productivity in a tiny 4x4 form factor. Small enough to fit in your hand, each NUC is silent and stackable. They can sit on a bookshelf, or be mounted to a wall with the VESA bracket or directly on the back of a monitor.

I've always thought these NUCs would make great Hyper-V clusters, but until just recently they were under powered and could only hold a maximum of 16GB RAM. Now there are two brand new Intel 32GB models that make this a really exciting Hyper-V lab possibility:
  • Intel NUC Kit NUC6i5SYH - Features a 6th generation dual core Intel Core i5-6260U with Intel Iris 540 graphics; Up to 32GB DDR4 RAM; Up to one M.2 and one 2.5" internal drives
  • Intel NUC Kit NUC6i7KYK - Features a 6th Generation quad core Intel Core i7-6770HQ with Intel Iris Pro 580 graphics; Up to 32GB DDR4 RAM; Up to two M.2 internal SSD drives
Both NUCs use the same storage format -- a 256GB M.2 SSD for the OS, and a 512GB SSD to run high performance VMs. With disk deduplication enabled, you can host many VMs on each node. When configured as a Hyper-V cluster, you can enable true high availability and enable new scenarios, like Hyper-V Live Migrations and Hyper-V Replication.

I also recommend using a portable 1TB USB3 external hard drive that you can share out for storing ISOs, software applications, and base images (see below). Each NUC has 2x USB 3.0 and 2x USB 2.0 ports for fast I/O performance, dual-band wireless-AC networking, 1GB NIC, Bluetooth, and built-in audio.

All you need to get started is buy the parts listed below and plug them in. They work pretty much straight of the box - no real assembly required. You'll only need to plug in the RAM and drives.

As usual, I link to Amazon for components and prices. Amazon does a very good job of maintaining stock, has an excellent return policy, and most of these items are eligible for free two-day shipping via Amazon Prime. If you don't have Prime, you can sign up for a free Amazon Prime trial here and cancel after you order the equipment if you want. Please note that it's normal for Amazon prices to fluctuate (usually down) over time.


NUC i5 Build #1 -- Intel Core i5 Dual-Core, 32GB RAM, SSD for $837 each
Component Description
 
Intel NUC Kit NUC6i5SYH (BOXNUC6I5SYH) Silver/Black
This is a 6th generation Intel Core i5-6260U dual core processor with Intel Iris graphics 540 (1.9GHz up to 2.8 GHz Turbo, 4MB Cache, 15W TDP). Supports 1x M.2 Type M SSD and 1x 2.5" SSD. 1x full-size HDMI 1.4b and 1x Mini DisplayPort 1.2 ports. 7.1 surround audio via HDMI and Mini DisplayPort. Headphone and mic jacks. 2x USB 3.0, 2x USB 2.0, and SDXC slot with UHS-I support. Dimensions: 115mm x 111mm x 48mm (roughly 4.5" by 4.5" x 1.8" - super tiny!). 19V, 65W wall-mount multi-country AC-DC power adapter (IEC types A/C/G/I). 3 year limited warranty.
 
CRUCIAL TECHNOLOGY 32GB Kit (16GBx2) DDR4 2133 MT/s (CT2K16G4SFD8213)
1.2V quad channel 2133MHz DDR 400 SODIMM memory with low CL15 latency. Great RAM at a great price. Each package contains 2x 16GB SODIMMs (32GB total). Lifetime warranty.
 
Samsung 950 PRO Series - 256GB PCIe NVMe - M.2 Internal SSD (MZ-V5P256BW)
The next-generation Samsung 950 PRO delivers uncompromising power and performance. Next Generation M.2 SSD Based on NVMe Protocol (PCIe, Gen. 3, x4). Ultra-fast Sequential Read/Write Performance: Up to 2,200MB/s and 900MB/s Respectively. Random Read/Write IOPS Performance : Up to 270K and 85K Respectively. Ultimate Performance, Reliability, & Efficient Power Management Powered by Samsung V-NAND Technology. 5 year limited warranty.
 
Samsung 850 EVO 500GB 2.5-Inch SATA III Internal SSD (MZ-75E500B/AM)
500GB SATA III 6Gb/s SSD used for active VMs (the VMs I normally have running, like a Domain Controller, Exchange servers, Skype/Lync servers, etc.). Enabling Windows Server 2012R2 disk deduplication provides even more storage capacity! Delivers up to 98K IOPS 4KB random read / 90K IOPS 4KB random write speed. Mwahaha!! 3 year limited warranty.

Obviously, you'll need two of these NUCs if you want to cluster them and you can always choose to buy one now and cluster them later.
I always update the BIOS from the Internet before installing the OS. Once you install the OS, install and/or upgrade the drivers (especially the NIC) from the manufacturers' websites. Then install the Hyper-V role and you're off to the races!
You can host quite a few VMs on this system. As an example, my Gen6 32GB server runs Windows Server 2012 R2 with the Exchange 2013 Edge Transport role and the Hyper-V host server role. This server has been running 24x7 for over a year with the following virtual machines:
  • 1x Domain Controller (2GB dynamic RAM)
  • 2x Exchange 2016 servers in a DAG (4-6GB each)
  • 1x Exchange 2013 server (4GB)
  • 1x Exchange 2010 server (4GB)
  • 1x Lync 2013 server (4GB)
  • 1x Application server (2GB)
I run these VMs off the 500GB SSD with Windows Server 2012 R2 disk deduplication enabled for Virtual Desktop Infrastructure (VDI). This allows me to put 669GB of data on this 500GB drive and I still have 145GB free space left! See Windows Server 2012 Deduplication is Amazing! for information about configuring this.


Now if you're looking for the ultimate in NUC performance check out this Intel i7 quad-core NUC:

NUC i7 Build #2 -- Intel i7 Quad-Core, 32GB RAM, 2x M.2 SSD for $1,316 each
Component Description
 
Intel NUC Kit NUC6i7KYK Mini PC (BOXNUC6I7KYK1)
This is a 6th generation Intel Core i7-6770HQ quad core processor with Intel Iris graphics 580 (2.6GHz up to 3.5 GHz Turbo, 6MB Cache, 45W TDP). Supports 2x M.2 Type M SSDs. 1x full-size HDMI 2.0 and 1x Mini DisplayPort 1.2, Thunderbolt 3 ports. 7.1 surround audio via HDMI and Mini DisplayPort. Headphone and mic jacks. 2x USB 3.0, 2x USB 2.0, and SDXC slot with UHS-I support. Dimensions: 211mm x 116mm x 28mm (roughly 8.3" by 4.5" x 1" - the size of a small paperback book!). 19V, 120W wall-mount AC-DC power adapter. 3 year limited warranty.
 
CRUCIAL TECHNOLOGY 32GB Kit (16GBx2) DDR4 2133 MT/s (CT2K16G4SFD8213)
1.2V quad channel 2133MHz DDR 400 SODIMM memory with low CL15 latency. Great RAM at a great price. Each package contains 2x 16GB SODIMMs (32GB total). Lifetime warranty.
 
Samsung 950 PRO Series - 256GB PCIe NVMe - M.2 Internal SSD (MZ-V5P256BW)
256GB for OS. The next-generation Samsung 950 PRO delivers uncompromising power and performance. Next Generation M.2 SSD Based on NVMe Protocol (PCIe, Gen. 3, x4). Ultra-fast Sequential Read/Write Performance: Up to 2,200MB/s and 900MB/s Respectively. Random Read/Write IOPS Performance : Up to 270K and 85K Respectively. Ultimate Performance, Reliability, & Efficient Power Management Powered by Samsung V-NAND Technology. 5 year limited warranty.
 
Samsung 950 PRO Series - 512GB PCIe NVMe - M.2 Internal SSD (MZ-V5P512BW)
512GB for VMs. The next-generation Samsung 950 PRO delivers uncompromising power and performance. Next Generation M.2 SSD Based on NVMe Protocol (PCIe, Gen. 3, x4). Ultra-fast Sequential Read/Write Performance: Up to 2,500MB/s and 1,500MB/s Respectively. Random Read/Write IOPS Performance : Up to 300K and 110K Respectively. Ultimate Performance, Reliability, & Efficient Power Management Powered by Samsung V-NAND Technology. 5 year limited warranty.

This NUC just SCREAMS performance! If it was available with 64GB of RAM this would be my go-to build, hands down. Maybe next year. :)

I also recommend the following to complete your NUC Hyper-V lab builds:

NUC Server Build Recommended and Optional Components
Component Description
 
*Highly Recommended*
Western Digital 1TB Black My Passport Ultra Portable External Hard Drive - USB 3.0 - (WDBGPU0010BBK-NESN)
Secure portable USB 3.0 storage with optional 256-bit AES hardware encryption. Available up to 3TB. Pre-formatted with NTFS. No power supply required. Use this to store software installs, ISOs, golden masters of your VM images, etc. 3-year limited warranty.
 
Samsung 850 Pro 1 TB 2.5-Inch SATA III Internal SSD (MZ-7KE1T0BW)
Upgrade your 500GB SATA III 6Gb/s SSD used for active VMs to the 850 Pro 1TB SSD. Delivers up to 90K IOPS 4KB random read / 100K IOPS 4KB random write speed. 10 year limited warranty.
VicTsing Gold-Plated HDMI to VGA Converter Adapter for PC, Laptop, DVD, Desktop (VS1-VC38BVT-VD)
Ultra-mini HDMI to VGA converter converts video from HDMI to any monitor or projector with a VGA port. Useful if you have an old-school KVM that doesn't support HDMI or DisplayPort.
 
Cable Matters Mini DisplayPort (Thunderbolt™ 2 Port Compatible) to HDMI/DVI/VGA Male to Female 3-in-1 Adapter in Black - Supporting 4K Resolution via HDMI
Lightweight and portable adapter for connecting a Mini DisplayPort (Mini DP or mDP)/Thunderbolt 2 port compatible computer to an HDTV, monitor, or projector with HDMI/DVI/VGA; A separate HDMI/DVI/VGA cable is required. Transmits both audio and video from computer or tablet to HD display via HDMI; Supports video resolutions up to 4K via HDMI or 1920x1200 and 1080p (Full HD) via VGA/DVI and flawless audio pass-thru for uncompressed digital 7.1, 5.1 or 2 channels.

I hope these NUC builds give you the confidence to build your own Hyper-V home cluster. I'm interested to hear your experiences in the comments section below. Happy building!
Read more ...

Turning a Disaster Recovery Test into a Disaster

Monday, October 27, 2014

I recently assisted a customer with a disaster recovery test for Exchange 2013 that went very wrong. I'm sharing what happened here in case the same unfortunate series of events happen to you so you know how to recover from it, or better yet maybe prevent it in the first place.

The customer's Exchange 2013 environment consists of a three node DAG, two nodes in the primary datacenter and another in the DR datacenter. The DAG is configured for DAC mode. The customer wisely wanted to test the DR failover procedures so they know what to expect in case the primary datacenter goes offline.

The failover process went smoothly. The SMTP gateways and Exchange 2013 servers in the primary datacenter were turned off and the DAG was forced online in the DR datacenter. Internal and external DNS was then updated to point to the DR site. CAS connectivity and mail flow was tested successfully from all endpoints - life was good. The customer wanted to leave it failed over to the DR site for a few hours to confirm there were no issues. 

Now it was time to fail back. The documentation says to confirm that the primary datacenter is back online and there's full network connectivity between the Exchange servers in both sites. Then login to each DAG member in the primary site and run "cluster node /forcecleanup" to ensure the servers are ready to be rejoined to the DAG.

But the customer scrolled past the part about where to run the command and ran it on the only node in the DR site. This essentially wiped the cluster configuration from the only node that held it. Instantly, the cluster failed and all the databases went offline. Since no other cluster nodes were online there was nothing to fail back to.

We fixed it by turning on the two DAG members in the primary site and starting the DAG in that site. That brought the databases online, but they were not up to date. We used the Windows Failover Cluster Manager console to evict the DR node and then add it back in. After AD replicated we saw that replication between all three nodes was working and the databases came up to date from Safety Net. We didn't even need to reseed any of the database copies. Disaster averted.

So how did this happen and what can be done to prevent it?

Human nature is to skip large blocks of text and read for the steps that need to be done. This is especially true when you're fairly comfortable with the steps or you're under pressure. For this reason, I keep my procedures pretty concise with maybe a sentence or two explaining why this step or procedure is being done.

In this case, the customer scrolled past the text explaining where to run the command and just ran it from the wrong server.

Here are my suggestions for creating disaster recovery documentation.

  • Know your audience. You need to make an assumption about who will be reading the DR documentation. Will it be the same people who manage the infrastructure in the primary site? Maybe not, if this is a true disaster. Make sure you write the documentation for the right audience. Avoid acronyms that unfamiliar users may not know, or at least spell if out once and then add the acronym the first time you use it. For example, Client Access Server (CAS).
  • Keep your DR procedures concise. People skip walls of text. Murphy's Law says that DRs happen at the worst times and people don't want to read a bunch of background information that's not pertinent to the task at hand. In a real disaster there will probably be a lot of other things going on and management asking for status. You might want to write your procedures like a cookie recipe. You don't need to be a chef to follow a recipe, but you do need to know how to fix it if something in the recipe goes wrong. Provide links in the documentation that reference TechNet concepts, as needed.
  • Highlight important steps. Use highlighting to call out important steps in the procedures, but don't overdo it. Too much highlighting will make it difficult to read. You can highlight using color or simple blocks of text, such as:
Important: The following procedures should be run from SERVER1.
  • Make sure the steps read top to bottom. Don't bounce around in the document or refer to previous steps unless it's something like, "Repeat for all other client access servers." Avoid procedures like, "Cut the blue wire after cutting the red wire." Try not to allow page breaks between important steps, if possible.
  • Use targeted commands, when possible. If a command can be targeted to a specific object it won't run if the object is unavailable. For example, the command "cluster node SERVER1 /forcecleanup" will run only if SERVER1 is up, rather than assuming the user is running it from the correct server. This particular suggestion would have prevented the unexpected outage in my example.

Read more ...

How to Rename an Existing DAG in Exchange 2010

Saturday, September 15, 2012
Technically you can’t rename an existing Database Availability Group, but you can recreate it with a new name.  It's possible to do this without requiring that the databases within the DAG to reseed.

Here are the steps to recreate a DAG with a new name:
  • Suspend all backups and disable circular logging if it's enabled.  This will ensure you have all the transaction logs required to update the database copies when you're done.

  • Remove all database copies from the DAG.  This will remove them from the DAG, but doesn’t actually delete the database files on the server.
Remove-MailboxDatabaseCopy -Identity DB01\MBX3
  • Remove all nodes from the DAG using the -ConfigurationOnly switch.  The Mailbox servers will be evicted from the DAG's cluster and removed from the DAG object in Active Directory.
Remove-DatabaseAvailabilityGroupServer -Identity DAG -MailboxServer MBX3 -ConfigurationOnly
  • Remove the DAG.  Now that the DAG has no members, it can be deleted from Exchange and Active Directory.
Remove-DatabaseAvailabilityGroup -Identity DAG
  • Clean up the cluster service on each node.  This restores the configuration of the Cluster service on the specified node to its original state.
cluster node /force
  • Restart the Microsoft Exchange Replication service on each node.  Now each server is in standalone.  Databases should mount and be accessible.
Restart-Service MSExchangeRepl
  • Create the DAG with the new name.  Ensure your DAG properties and network settings are correct.
New-DatabaseAvailabilityGroup -Name DAG3 -WitnessServer EXHUB2 -DatabaseAvailabilityGroupIPAddresses 10.0.0.8,192.168.0.8
  • Add the nodes to the new DAG.
Add-DatabaseAvailabilityGroupServer -Identity DAG3 -MailboxServer MBX3
  • Add mailbox database copies.  Exchange will see that the database copies already exist in the target file system and will resume replication.
Add-MailboxDatabaseCopy -Identity DB01 -MailboxServer MBX3 -ActivationPreference 3

As long as there wasn’t a tremendous amount of data churn (>~10%) you won’t need to reseed the databases.  Exchange will just replicate the logs generated from the time you removed the database copies.

Remember to resume your Exchange backups and reconfigure circular logging if it was previously enabled.
Read more ...

Exchange 2010 DAG Always Replicates from Active Database

Wednesday, August 29, 2012
Today's article is a tidbit of information, but important to call out for larger scale DAG deployments.

Exchange 2010 always uses the active database in the DAG as the source for log shipping during normal replication.  That means that if you have multiple passive copies in your DAG, Exchange ships transaction logs from the active copy to each passive copy, even if some of the copies are in the same site.  There is no peer-to-peer log shipping between passive copies in a DAG.

Simple four node DAG with three passive copies
In the example above we have a single DAG with the active database and one HA copy in DC1, and one DR copy and a lagged copy in DC2.  Log shipping occurs from the active database to the three passive copies, traversing the WAN twice for the copies in DC2.

This can have quite an affect on a complex enterprise deployment with multiple DAGs and many remote passive copies, so keep that in mind for your designs.

Note: Log shipping is different than seeding.  Seeding is a file copy of the database to another server.  Once seeding completes log shipping is used to keep that copy up to date. It is possible to seed a database from a specific server, perhaps one in the same site.  For more information see the "Selecting the Seeding Source" topic in http://technet.microsoft.com/en-us/library/dd335158.aspx.


Read more ...

How to Seed an Exchange 2010 Database from a Particular Source

Thursday, May 10, 2012
Normally when you seed (copy) an Exchange database in a DAG, the source is the active database.  This may not be efficient if the source database is across the WAN.  This article explains how to seed from a different source, preferably a passive copy in the local LAN.

Seeding a database copy can be performed from the Exchange Management Console (EMC) or the Exchange Management Shell (EMS).  The database will always seed from the active database when you perform the operation from the EMC.  If you want to select a different source you need to use EMS.

Open and elevated EMS prompt and run the following three cmdlets:

Add-MailboxDatabaseCopy -Identity DB01 -MailboxServer EXMB03 -SeedingPostponed

Suspend-MailboxDatabaseCopy -Identity DB01\EXMB03 -SuspendComment "Seed DB01 from EXMB02" -Confirm:$False

Update-MailboxDatabaseCopy -Identity DB01\EXMB03 -SourceServer EXMB02 -DeleteExistingFiles

The first command adds a new mailbox database copy of database DB01 on mailbox server EXMB03, but does not start the seeding operation.  Once this operation completes you will see the DB01 database copy on EXMB03 will be in a "Failed and Suspended" state.

The second command suspends the mailbox database copy and creates a suspend comment.  This step is not necessary, but it's helpful to create a comment so other administrators don't try to "fix" the failed and suspended database copy.

The third command seeds the mailbox database copy on EXMB03 from the source server EXMB02.  It also deletes any existing DB01 database or log files on the target prior to seeding.  Once this operation begins the database copy state will change to "Seeding" until the seeding operation is complete, at which point it will change to "Healthy".
Read more ...

Exchange 2010 support for host-based failover clustering and migration

Tuesday, January 24, 2012

Some Exchange-supported virtualization platforms, such as Hyper-V and VMware include features that support the clustering or portability of guest virtual machines across multiple physical root machines.  Examples of host-based failover clustering and migration include Hyper-V Live Migration and VMware ESX vMotion.

Microsoft support for host-based failover clustering and migration virtualization with Database Availability Groups (DAGs) depends on the Exchange 2010 service pack level.  Per the Exchange 2010 System Requirements:

With Exchange 2010 RTM:

Microsoft doesn't support combining Exchange high availability solutions (such as DAGs) with hypervisor-based clustering, high availability, or migration solutions that will move or automatically failover mailbox servers that are members of a DAG between clustered root servers. DAGs are supported in hardware virtualization environments, provided the virtualization environment doesn't employ clustered root servers, or the clustered root servers have been configured to never failover or automatically move mailbox servers that are members of a DAG to another root server.

With Exchange 2010 SP1 (or later) deployed:

Exchange server virtual machines (including Exchange Mailbox virtual machines that are part of a DAG), may be combined with host-based failover clustering and migration technology, as long as the virtual machines are configured such that they will not save and restore state on disk when moved, or taken offline. All failover activity must result in a cold boot when the virtual machine is activated on the target node. All planned migration must either result in shutdown and cold boot, or an online migration that makes use of a technology like Hyper-V Live Migration. Hypervisor migration of virtual machines is supported by the hypervisor vendor; therefore, you must ensure that your hypervisor vendor has tested and supports migration of Exchange virtual machines. Microsoft supports Hyper-V Live Migration of these virtual machines.

In summary, Exchange 2010 SP1 or better supports hypervisor migrations such as Hyper-V Live Migration and VMware ESX vMotion for DAG member servers.  Host-based failover cluster migrations, such as Hyper-V Quick Migration, is supported only if the virtual Exchange DAG server is restarted immediately after the quick migration completes.  Exchange 2010 RTM is not supported with either migration technology.  RTM only supports the native Exchange high availability features present in DAGs.

Other Exchange Server 2010 roles (CAS, Hub Transport, Edge Transport, and Unified Messaging) fully support host-based failover clustering and migration because they do not employ native Exchange high-availability solutions.

For a list of the virtualization platforms supported by Exchange, visit the Windows Server Virtualization Validation Program website.
Read more ...

Failure of FSW Causes Cluster Group to Failover

Friday, June 12, 2009

The following information was written for Exchange 2007 CCR mailbox clusters, but it pertains to any clustering solution that uses the Windows Server 2008 Node and File Share Majority cluster quorum configuration.

How Does Node and File Share Majority Clustering Work?

Exchange 2007 CCR uses two clustered Exchange mailbox nodes, called a Clustered Mailbox Server (CMS). In order for Windows to know which node is active, it utilizes a File Share Witness (FSW) to maintain quorum. The FSW is a network share on a third computer (typically a Hub Transport server in the normally active node's physical site). The active node writes information to files in that share and locks them for writing, preventing the passive node from writing to the FSW and taking quorum. It always take two out of three votes to maintain quorum.

If the active node becomes unavailable, the passive node can write to the FSW and the cluster group fails over. In the case of a total site failure where both the active node and the FSW are offline, both the cluster group and the CMS will fail since there is no quorum (there's only one vote).

What Happens When the FSW Becomes Unavailable?

When the FSW fails, the active CMS node (Exchange) does not fail over because there are still two votes (the active and passive nodes). However, the Windows cluster group will fail over to the other node if the FSW does not come back online within 60 seconds. This is because File Share Witness resource in Windows Server 2008 is configured to fail over the cluster group when the FSW fails, as shown below.


Worse, the FSW resource will not come back online for another 60 minutes. During this time, a failure of either one of the nodes will cause the cluster to fail, even if the FSW is back online.

These default settings are provided so that the cluster event logs don't fill up with constant "Trying to start the resource", "The resource failed to start" events during a prolonged outage.

This is what happens when the FSW server is rebooted (during patch management, for example):

  • The server holding the FSW resource is rebooted.
  • The cluster tries to connect to the FSW one minute after failure is detected.
  • If the FSW is still unavailable (which usually happens - most servers take longer than 60 seconds to restart), the cluster group fails over to another node.
  • Wait one hour and try connecting to the FSW again. The FSW is finally brought online.
Note: This behavior only pertains to Windows Server 2008. Windows Server 2008 R2 does not have this issue.

It's important to know that even though the cluster group fails over, there really is no effect on Exchange, even with a geographically disbursed CCR cluster (geo-cluster). However, if you're like me, you like symmetry and order. The cluster group should be with the active CMS node.

Here's how to minimize the time that the cluster group is on the (normally) passive node:

  • Open the Failover Cluster Management console
  • Add the cluster name, if necessary, and select it
  • Double-click Cluster Core Resources in the middle pane to expand it
  • Right-click File Share Witness (\\servername\sharename) and select Properties
  • Click the Policies tab
  • For optimal restart performance, change "If all the restart attempts fail, begin restarting again after the specified period (hh:mm)" to 15 minutes, as shown below:

This configuration will cause the cluster service to attempt to bring the FSW resource to online once every 15 minutes, instead of an hour.

Next, logon to the server holding the FSW resource (typically a Hub Transport server in the active site and install the Failover Clustering Tools feature. You'll find it in Remote Server Administration Tools > Feature Administration Tools.

Now create a batch file called FSW_Online.bat. Enter the following two lines:

  • cluster EXCLUSTER1 res "File Share Witness (\\server\mns_fsw_excluster1)" /online
  • cluster EXCLUSTER1 group “Cluster Group” /move:node.yourdomain.com

Note: Replace EXCLUSTER1 with your cluster name. Replace \\server\mns_fsw_excluster1 with the name of your FSW resource (enter "cluster res" at a command prompt to find it). Replace node.yourdomain.com with the FQDN of the CMS node you want to keep the cluster group on.

Lastly, configure FSW_Online.bat to run at startup on the FSW resource server:

  • Open Local Group Policy Editor
  • Navigate to Computer Configuration > Windows Settings > Scripts (Startup/Shutdown) > Startup
  • Click Add and browse to the FSW_Online.bat file you created
  • Click OK twice and close Local Group Policy Editor

This is my current best practice for configuring the File Share Witness resource failure policy.

Special thanks go to Tim McMichael, Senior Support Escalation Engineer on the Exchange product support team, for assisting me with this article.

Read more ...

How To Enable Change Notification On All Site Links

Wednesday, March 18, 2009

Normally, there are two replication intervals for Active Directory in a Windows domain: Intra-site (replication between DCs in the same site) and Inter-site (replication between DCs in different Active Directory sites).
Intra-site replication is very fast - typically around 15 seconds. This schedule can be configured via the registry using the following values in the HKLM\SYSTEM\CurrentControlSet\Service\NTDS\Parameters key:

Replicator notify pause after modify (secs)It is a REG_DWORD value of 15 by default
Replicator notify pause between DSAs (secs)It is a REG_DWORD value of 3 by default
See Microsoft TechNet (Active Directory Replication Tools and Settings) for a thorough explanation of what these keys do.Inter-site replication is dictated by the schedule associated with the replication connection in Active Directory Sites and Services. Using this GUI you can specify that the connector never replicates or to replicate once, twice or four times per hour.
Note: The inter-site replication schedule runs based on the server startup time. For example, if the DC starts up at 12:10pm and the replication connector's schedule is set to twice per hour, replication on this connector will occur at 12:10pm, 12:40pm, etc.
But what if you want Intersite replication to occur more frequently than every 15 minutes? For this, you must enable Change Notification on the Active Directory site link. How you do this depends on which OS is on your DC.

For Windows 2003 Domain Controllers:
  • Open ADSIEdit.msc (in the Windows Support Tools) as a Domain Admin
  • Open the Configuration naming context
  • Navigate to Sites > Inter-Site Transports > IP
  • Right-click the siteLink to modify in the results pane and click Properties
  • Locate the options attribute and edit the value from 0 to 1
  • Click OK and repeat for other siteLinks, as necessary.

For Windows 2008 and Windows 2008 R2 Domain Controllers:
You can use the same method as Windows Server 2003 DCs or you can edit the values directly from AD Sites and Services, as follows.
  • Locate the Inter-Site Transport site link to modify, typically DEFAULTIPSITELINK, in AD Sites and Services
  • Right-click the site link and choose Properties
  • Click the Attribute Editor tab
  • Locate the options attribute and edit the value from 0 to 1
  • Click OK and repeat for other Site Links, as necessary.
I also wrote two VBScripts for displaying and configuring Change Notification:
  • DisplayChangeNotification.vbs displays the current value of the options attribute on each site link in the Active Directory domain where it is run.
  • EnableChangeNotification.vbs will enable Change Notification on all site links in the Active Directory domain where it is run by changing the options value to 1.
Both scripts are in the ChangeNotificationScripts.zip file, located here.
Read more ...

Top Ten Reasons to Move to Exchange 2007

Tuesday, February 26, 2008
Here are some key features and technologies Exchange Server 2007 provides that make a good business case for its use:
  • Fault Tolerance -- Exchange 2007 offers several forms of fault tolerance, right out of the box:

    • Local Continuous Cluster (LCR) maintains a continuously updated copy of the active mailbox database on a different LUN to provide immediate failover capability if the active database becomes corrupt. The second copy is activated manually by the administrator.

    • Cluster Continuous Replication (CCR) is a local cluster model where each node maintains its own database and replication is performed using log shipping. In the event of failure of a service, the cluster services immediately failover to the passive node and continue servicing client requests, minimizing client downtime. CCR clusters can be stretched over distance, providing a geographically dispersed clusters.

    • Standby Continuous Replication (SCR) is similar to CCR, but the failover node resides in a different geographic location. It utilizes log shipping for replication and the Hub Transport servers "fill in the blanks" for messages that may not have replicated since the time the active node went offline.


  • Disaster Recovery -- Outlook 2003 and Outlook 2007, along with the fault tolerance technologies listed above, provide a quick and easy disaster recovery strategy for nearly any outage. Outlook Exchange cached mode is another key technology to making disaster recovery as seemless as possible.


  • Mailbox Server Consolidation -- As a 64-bit messaging platform, Exchange 2007 is able to accommodate much larger mailboxes and mailstore databases than ever before. This allows you to greatly consolidate the number of mailbox servers needed to support the same number of users.


  • Exchange Edge Server -- Edge Server for Exchange is a non-domain server that acts as the SMTP gateway between the Internet and SCIF's internal network. It replaces both the current SMTP gateway and Interscan servers, saving both hardware and software costs. It provides anti-spam and anti-virus services for the organization. EdgeSync is a process that synchronizes the email addresses in AD and the user Junk Mail safe lists/block lists with the Edge server to reduce spam at the network edge.


  • Better Integration with Outlook -- Suspected spam that is not blocked by the Edge server is delivered to Outlook's built-in Junk E-mail folder. Users can choose to block or allow emails from users or domains directly from Outlook without the need for third-party software.


  • Forefront Security for Exchange -- Forefront antivirus is included with the Exchange 2007 Enterprise CAL. Forefront allows you to choose up to five different antivirus engines (from a collection of nine) that all emails are scanned against. This provides more defense in depth than previously possible.


  • Corporate Manage Folders -- Managed folders allow administrators to configure common corporate folders that will display in users' Outlook and OWA that have specific retention periods. For example, a folder named Legal may have a seven year retention policy. Any items in this folder older that 7 years will automatically be purged to maintain the company's corporate retention policy.


  • Improved Outlook Web Access -- Outlook Web Access (OWA) has been improved to provide much better performance and usability. The Private computer security setting now allows you to stay logged in for up to 24 hours. Calendaring and scheduling has been greatly improved. OWA now provides the ability to open another user's mailbox (assuming you have the appropriate rights to do so). Public Folders now open in the same OWA window. Searching for an email items takes only seconds, no matter how large the mailbox is.


  • Remote Access to Network Shares -- OWA provides the ability to "translate" UNCs to internal network shares. For example, if you click a link for //hofs01/share/CIOMeeting.ppt, OWA will fetch the document from the internal network (assuming you have rights to the document) and deliver it to you in OWA. You can also open a Windows SharePoint Services or file share by typing the address of the share to open directly in OWA.


  • WebReady Document Viewing -- WebReady Document Viewing renders common document types for you to view within OWA, even if the application is not installed on that computer. For example, if you want to view an Excel attachment from a machine that does not have Excel installed, click the "View as web page" link next to the attachment. Exchange 2007 will convert the spreadsheet to a web page for you to review.


Read more ...

Exchange 2007 High Availability Sessions

Thursday, June 7, 2007
Today was an "all Exchange, all the time" day. The sessions I attended dealt with Exchange 2007 high availability and disaster recovery.

One was presented by Ayla Kol entitled, "High Availability in Microsoft Exchange Server 2007 and Exchange Server 2007 Service Pack 1". She did a good job explaining what's offered in E2K7 RTM for HA and went on to explain what's going to be new in SP1. Here are the highlights for RTM:
  • Windows 2003 needs KB921181 to enable File Share Witness (FSW)
  • Continuous Cluster Replication (CCR) is limited to 2 nodes
  • CCR requires hardware from the Geographically Dispersed Cluster category of the HCL
  • FSW should be on hub in primary site
  • CCR nodes must be in the same subnet. This poses a problem for geo-clustering
  • Best Practice to use a CNAME record for the FSW name. This provides easier failover
  • Best Practice to increase tolerance of heartbeat failures to 10
  • Log shipping to the passive node is a pull model. The Replication Service monitors logs
  • Divergence = loss of mailbox data. This is what happens in a "lossy" recovery. Normally, in CCR the hub's transport dumpster will backfill the recovered node with missing data.
  • LLR = lost log resilience. This is what the transport dumpster is for.
  • The transport dumpster works only with CCR in RTM. It will work with LCR in SP1
  • Recovery from transport dumpster is designed to backfill within 30 seconds
  • SP1 will have a GUI for cluster management (finally!)

And now for what we've all been waiting for, Single Copy Replication (SCR)!

  • SCR will be included in SP1
  • Possible scenarios include: Standalone server to SCR, LCR to SCR, and CCR cluster to SCR
  • Designed for datacenters
  • CCR can use dissimilar hardware. This offers simplified hardware and storage requirements. Does not require hardware from the Geographically Dispersed Cluster category of the HCL
  • No subnet requirements! Can work across different subnets, unlike CCR
  • Only works with one database per storage group
  • Must be same paths

In a future blog, I hope to write more about CCR and SCR. For now, we're off to the TechEd attendee party at Islands of Adventure. The kids are gonna have a blast!

Read more ...